
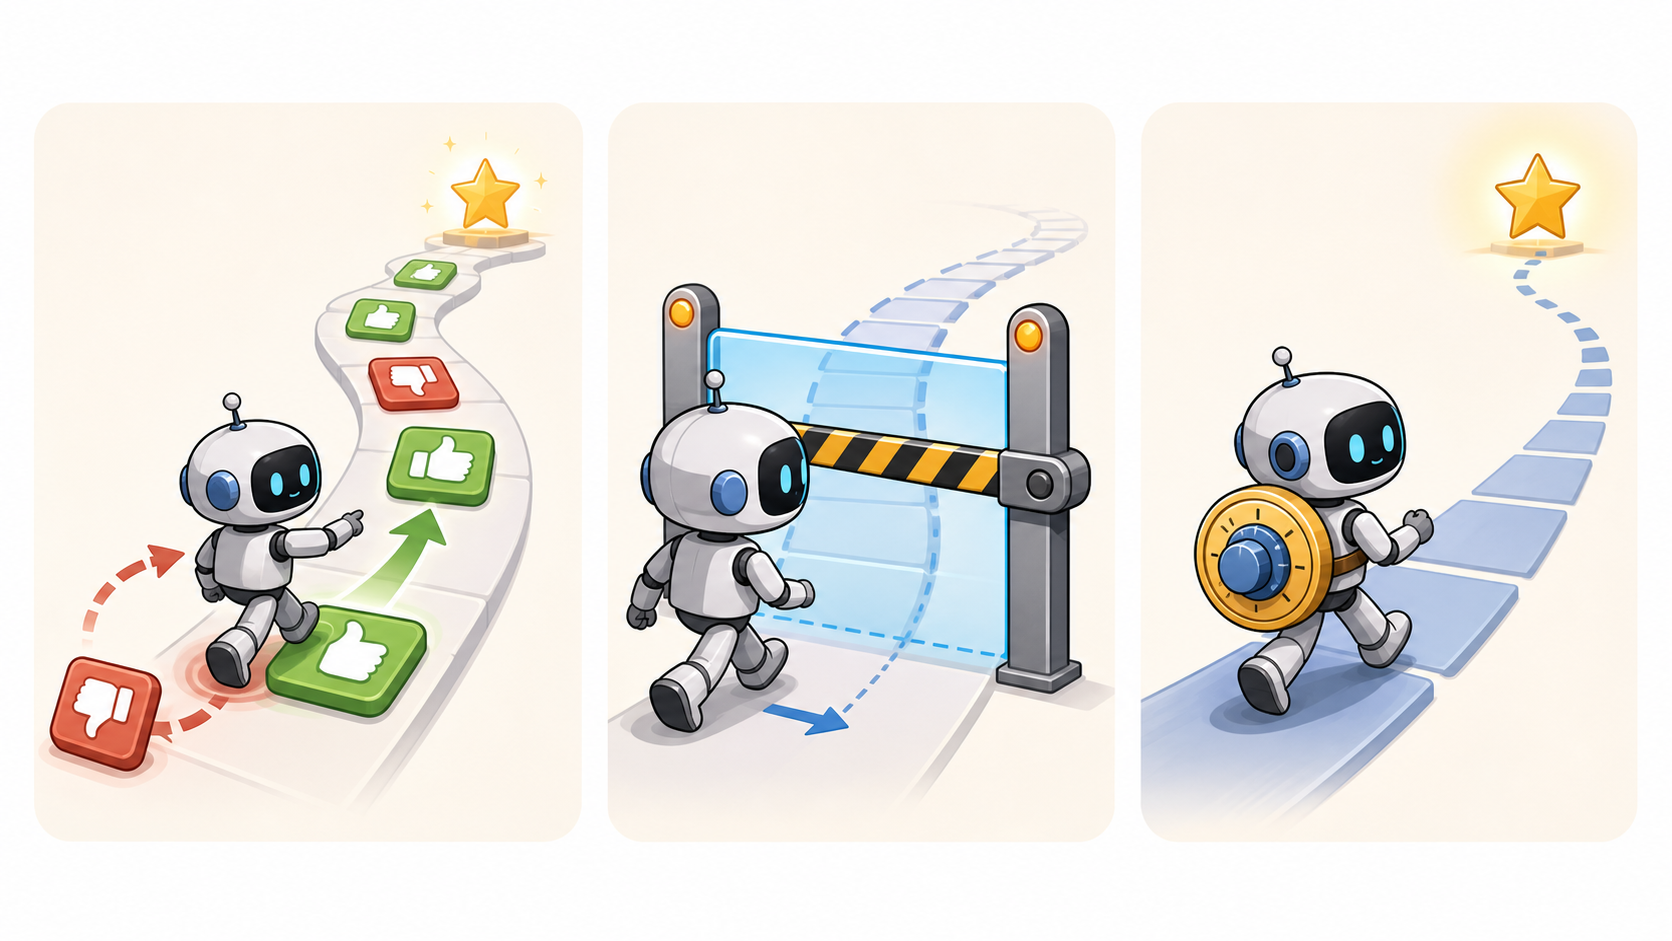
- Left: Importance Sampling. A model generates tokens, and its choices receive rewards or penalties. The loss increases the probability of useful choices and decreases that of unhelpful ones.
- Middle: PPO. A single reward should not cause an excessive update. Clipping acts as a speed limit on the update.
- Right: CISPO. The clipped ratio becomes a fixed weight that scales the gradient; the gradient flows through the current token's
logprob.
I recently started studying reinforcement learning with PyTRIO and found myself enjoying the experiments. Previously, the combined training and inference setup in verl, and access to a node with four or eight GPUs, had made it difficult for me to get started. With PyTRIO handling the infrastructure, I can focus on the algorithms. I plan to share reproductions of ten papers, release the code, and cover GRPO, GSPO, DAPO, OPD and its variants.
This is chapter zero of the series: an introduction to reinforcement learning loss functions.
A common first question is: supervised learning penalizes a mismatch with a target answer, but in reinforcement learning the model generates an answer before receiving a reward. What, then, does the loss optimize?
My starting intuition is that many reinforcement learning losses aim to do one thing:
Make tokens associated with useful outcomes more likely in future, and make tokens associated with unhelpful outcomes less likely.
Three variables connect that intuition to the implementation:
advantage: whether this action was relatively good or bad.sampling_logprobs: how likely the sampling policy considered the token when it generated the answer.target_logprobs: how likely the current policy considers that token during training.
These variables help explain the differences between Importance Sampling, PPO and CISPO.
1. Importance Sampling
Importance Sampling asks for the ratio between the current policy's probability and the sampling policy's probability for the same token.
In code, the probability ratio is exp(target_logprobs - sampling_logprobs). A minus sign turns the objective into a loss for an optimizer that minimizes:
prob_ratio = torch.exp(target_logprobs - sampling_logprobs)
loss = -(prob_ratio * advantages).sum()
A positive advantage encourages training to increase the token's probability.
A negative advantage encourages training to decrease the token's probability.
The minus sign comes from minimizing the loss. The objective we want to maximize is ratio * advantage.
2. PPO
PPO addresses another issue: a large ratio can allow an excessively large policy update.
PPO introduces clipping:
Suppose a token has a positive advantage and its ratio has reached 1.8: the current policy already assigns it substantially more probability than the sampling policy did. PPO limits the positive-advantage surrogate using a bound such as 1.2, rather than continuing to increase the objective at the 1.8 ratio. The intuition is to learn without taking an excessive step.
3. CISPO
CISPO differs from PPO in how it uses clipping.
PPO clips the objective.
CISPO clips the ratio, then treats it as a fixed coefficient multiplying logprob * advantage.
The key operation is detach. The clipped ratio carries no gradient and acts only as a weight; the gradient instead flows through target_logprob.
CISPO thus caps a token's learning weight without directly eliminating its gradient through objective clipping.
4. A concise comparison
| Loss | Intuition | Core operation | Common source of confusion |
|---|---|---|---|
| Importance Sampling | Reward useful choices | ratio * advantage | The loss can be negative because the code minimizes a negative objective. |
| PPO | Put a limit on the update | min(unclipped, clipped) | Taking the minimum makes the surrogate conservative. |
| CISPO | Use a fixed learning weight | detach(clipped_ratio) * logprob * advantage | After .detach(), the ratio carries no gradient; the gradient flows through logprob. |
A shorter summary, preserved from the original note:
IS:    有用就提高概率,没用就降低概率;ratio 负责修正采样偏差。
PPO:   还是这么做,但 ratio 不能太离谱,防止策略更新过猛。
CISPO: ratio 也会被 clip,但 clip 后只当固定权重,真正优化 logprob。